System prompt architecture
Role, constraints, output contract, refusal and uncertainty behaviour, and examples chosen to teach the edges rather than the obvious.
Prompts designed against a test set, not a vibe.
System prompt architecture, structured output contracts and graded evaluation sets — so a prompt change is a measured improvement rather than a hopeful edit.
What you receive
Overview
Prompt work goes wrong in a predictable way. Someone edits the prompt, the one example they check looks better, it ships, and three other things quietly break.
We treat prompts as versioned artefacts with tests. First an evaluation set from your real inputs and a graded baseline; then changes measured against it. You end up knowing not just that output improved, but by how much and where it still fails.
Technologies
Each choice is made per engagement and written down with its reasoning.
Problems we solve
If one of these describes your situation, this is the right page.
We find which part of the instruction is ambiguous, tighten the contract, and verify the fix across a whole test set instead of one example.
Structured output with a schema and validation turns 'usually JSON' into a contract your code can depend on.
A graded evaluation set makes regressions visible before release, so iteration stops being a gamble.
Shorter prompts, caching, and routing easy cases to a smaller model usually cut cost substantially with no quality loss.
Capabilities
Concrete capabilities rather than adjectives. Anything not listed here, we will tell you we do not do.
Role, constraints, output contract, refusal and uncertainty behaviour, and examples chosen to teach the edges rather than the obvious.
Schemas, tool-call formats and validation so downstream code gets predictable data instead of prose it has to parse.
Representative cases drawn from your real inputs, with explicit grading criteria and a recorded baseline.
Context assembly, chunk ordering, citation behaviour and the 'not in the provided context' rule for RAG systems.
Prompt compression, caching strategy and model routing, measured against the same evaluation set.
A prompt library with usage notes, a change process, and a working session so your team can maintain it.
Process
Specific to this service. The wider seven-stage delivery process wraps around it.
What the model must do, what good output looks like, and what must never happen.
Real inputs including the awkward ones, with grading criteria agreed up front.
Current prompts graded, so improvement is measured from a known starting point.
Changes made one variable at a time, with results recorded per change.
Final prompts, evaluation harness, cost analysis and a working session with your team.
Related work
Entries marked as a content placeholder are reserved for projects whose details are not yet published.
A documented prompt system for product descriptions, email sequences and ad copy, with A/B tested variants.
200+ prompts delivered · 60% faster content production · Consistent across channels brand voice
 Custom AI Agents
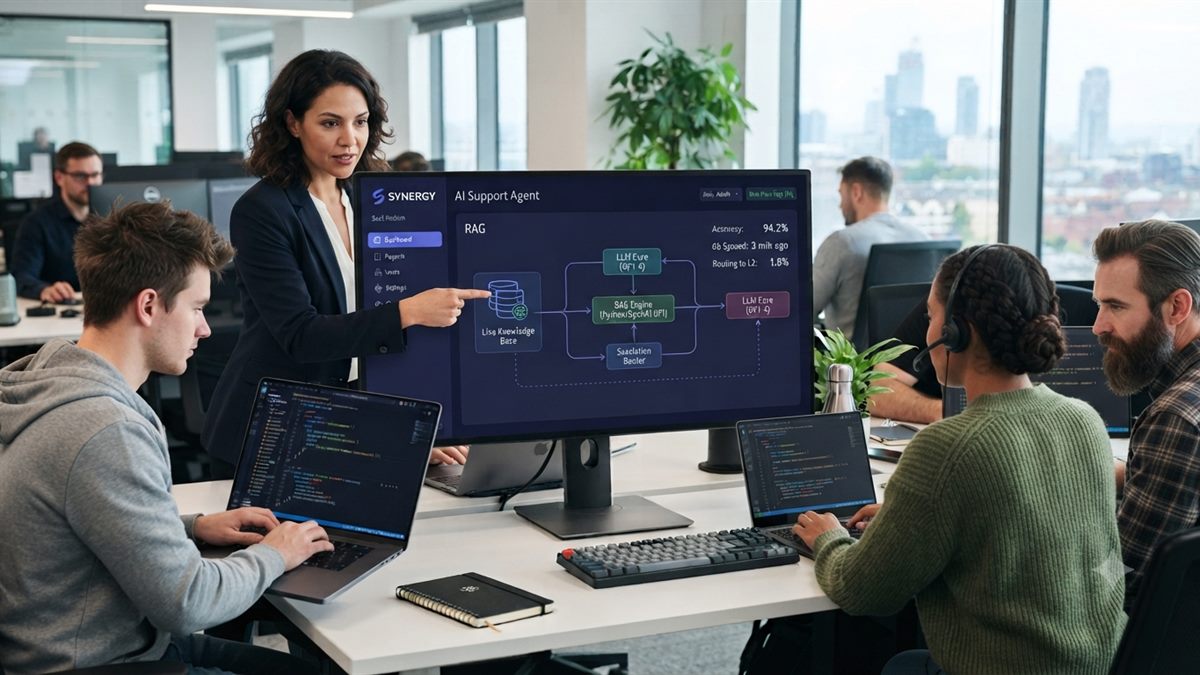
A retrieval-grounded support agent handling FAQs, order status and product questions, with escalation to the human team.
70% fewer support tickets · 24/7 availability · Multilingual languages
Pricing
Indicative tiers. The final scope and a fixed quote are confirmed in writing after discovery — nothing starts on an estimate.
One use case, properly tested.
A prompt system across several use cases.
Ongoing prompt engineering alongside your team.
Questions
The questions we are actually asked about prompt engineering, answered without hedging.
The easy wins have moved, but the valuable part was never clever phrasing. It is specifying the task precisely, defining the output contract, and having an evaluation set that tells you whether a change helped. Better models make that work pay off faster, not less.
Your real inputs — including the awkward and ambiguous ones — with agreed grading criteria. Typically 30 to 100 cases depending on the task. It is yours to keep and extend, and it is the most durable thing we hand over.
Usually, yes. Shorter prompts, prompt caching, and routing simple cases to a smaller model are the common levers. We measure cost per case before and after against the same evaluation set, so a saving is never bought with silent quality loss.
Rarely as a first step. Prompting and retrieval solve most problems faster and cheaper, and remain easier to change. When fine-tuning genuinely is the answer — a narrow, high-volume, stable task — we will say so and explain the data you would need.
Partly. Structure, contracts and the evaluation set transfer; specific phrasing sometimes needs retuning. Because you keep the evaluation harness, re-validating against a new model is a short exercise rather than a rebuild.
Related solutions
Triage, extraction, drafting and research steps handled by grounded AI inside your existing processes — scoped narrowly, evaluated honestly, and escalated to people by design.
02Support automation grounded in your own help content, with confidence thresholds, source citations and a handover that arrives with context already attached.
Or browse all six services.
Tell us where you are now and what needs to be true in three months. You will get a written scope and a fixed quote before anything starts.
Prices shown exclude third-party costs such as hosting, model API usage and advertising spend, which are paid directly by you.