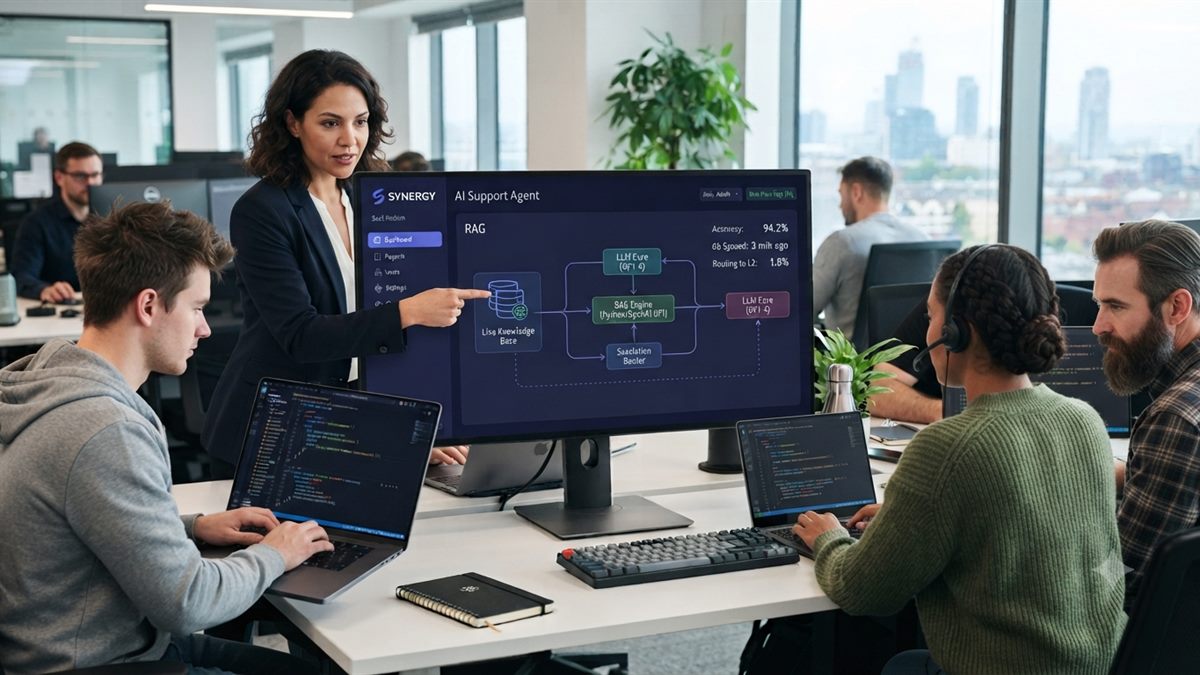
Retrieval-grounded agents (RAG)
Ingestion and chunking of your documents, embeddings, vector search, reranking and citation of sources in answers.
Agents with a defined scope, real tools and a tested failure path.
Support agents, document processing, lead qualification and multi-step workflows — built on retrieval over your own content, with evaluation and escalation designed in.
What you receive
Overview
An agent is only useful when its boundaries are clear. What it may read, what it may do, what happens when it is unsure, and who it hands to. Skip that and you get a confident system that invents answers.
We design the scope first, ground the agent in your own content through retrieval, give it a small set of real tools, and evaluate it against a test set of your actual questions before anyone outside the team uses it.
Technologies
Each choice is made per engagement and written down with its reasoning.
Problems we solve
If one of these describes your situation, this is the right page.
We ground responses in retrieval over your approved content and have the agent say it does not know and escalate, rather than fill the gap.
High-volume repetitive queries are handled automatically with a clean handover to a human for anything outside the defined scope.
Invoices, applications, CVs and contracts are extracted into structured, validated data with low-confidence cases routed for review.
We instrument every run — inputs, retrieved context, tool calls, cost and outcome — so quality is observable rather than anecdotal.
Capabilities
Concrete capabilities rather than adjectives. Anything not listed here, we will tell you we do not do.
Ingestion and chunking of your documents, embeddings, vector search, reranking and citation of sources in answers.
Typed tool definitions with validation and permission boundaries, so an agent can look things up and act without unbounded access.
Website, in-app and messaging channels, with intent routing, confidence thresholds and human escalation paths.
Extraction into Pydantic-validated schemas, confidence scoring and review queues for anything uncertain.
Pipelines that plan, call tools, verify intermediate results and retry — with hard stops instead of infinite loops.
A graded test set built from your real questions, regression runs on every prompt or model change, and cost and latency dashboards.
Process
Specific to this service. The wider seven-stage delivery process wraps around it.
We write down the questions and actions in scope, the ones out of scope, and the escalation rule.
Which sources the agent reads, how they stay fresh, and which systems it is allowed to touch.
Retrieval pipeline, prompts, tool layer and guardrails, developed against real examples.
Graded runs against your test set; we publish accuracy and failure modes rather than a demo.
Staged rollout with monitoring, then tuning based on logged real conversations.
Related work
Entries marked as a content placeholder are reserved for projects whose details are not yet published.
 Custom AI Agents
A retrieval-grounded support agent handling FAQs, order status and product questions, with escalation to the human team.
70% fewer support tickets · 24/7 availability · Multilingual languages
End-to-end automation of CRM sync, invoice generation, client onboarding, notifications and reporting.
15 hrs/week time saved · Eliminated manual data entry · Real-time team notifications
Pricing
Indicative tiers. The final scope and a fixed quote are confirmed in writing after discovery — nothing starts on an estimate.
A grounded assistant for one channel and knowledge base.
An agent that acts across your systems, not just answers.
Multiple agents, shared infrastructure, ongoing evaluation.
Questions
The questions we are actually asked about custom ai agents, answered without hedging.
Not through us. We use the providers' API tiers, which do not train on submitted data by default, keep retrieval content in storage you control, and document exactly what is sent to which provider so you can review it against your own policy.
Three things, together: answers are grounded in retrieved content with citations; the prompt and tooling make 'I don't know, let me hand this over' a first-class outcome; and a graded evaluation set catches regressions before they reach users. We also report the measured failure rate rather than claiming there is not one.
Whichever fits the task, cost and latency budget — usually Claude or GPT-class models, sometimes a smaller model for classification steps. We keep the model behind an abstraction so switching is a configuration change, not a rebuild.
Token and infrastructure costs are yours and depend on volume. We estimate them during scoping from the actual prompt and retrieval sizes, instrument real cost per conversation after launch, and will tell you when a cheaper model or a cache would do the same job.
Usually yes — anything with an API. Common integrations are CRMs, helpdesks, databases, spreadsheets and messaging platforms, either directly or through n8n. Where an MCP server gives cleaner, reusable access, we will say so.
Related solutions
Triage, extraction, drafting and research steps handled by grounded AI inside your existing processes — scoped narrowly, evaluated honestly, and escalated to people by design.
02Support automation grounded in your own help content, with confidence thresholds, source citations and a handover that arrives with context already attached.
03The recurring manual steps between your tools — copying records, chasing approvals, rebuilding the same report — rebuilt as reliable automations with error handling and logs.
Or browse all six services.
Tell us where you are now and what needs to be true in three months. You will get a written scope and a fixed quote before anything starts.
Prices shown exclude third-party costs such as hosting, model API usage and advertising spend, which are paid directly by you.